Prompt-level visibility
Which buyer questions already name you, and which skip you. The unit is the prompt, not a traffic chart. If the question that starts a meeting does not include you, the rest of the funnel never opens.
Product
The audit and tracking layer. GEOview shows what ChatGPT, Perplexity, Claude, and Google AI already say about your category, then whether placements move those answers. It is technology, never an engine.
Which buyer questions already name you, and which skip you. The unit is the prompt, not a traffic chart. If the question that starts a meeting does not include you, the rest of the funnel never opens.
How often you appear across the prompts that matter, next to the other names in that shortlist. An answer is a handful of companies. Share of answer is whether you are in that handful, not a vanity score we invented.
Who else the models already trust in your category, and which sources they cite for those names. This is a map of the public record, not an attack list and not a fake win rate.
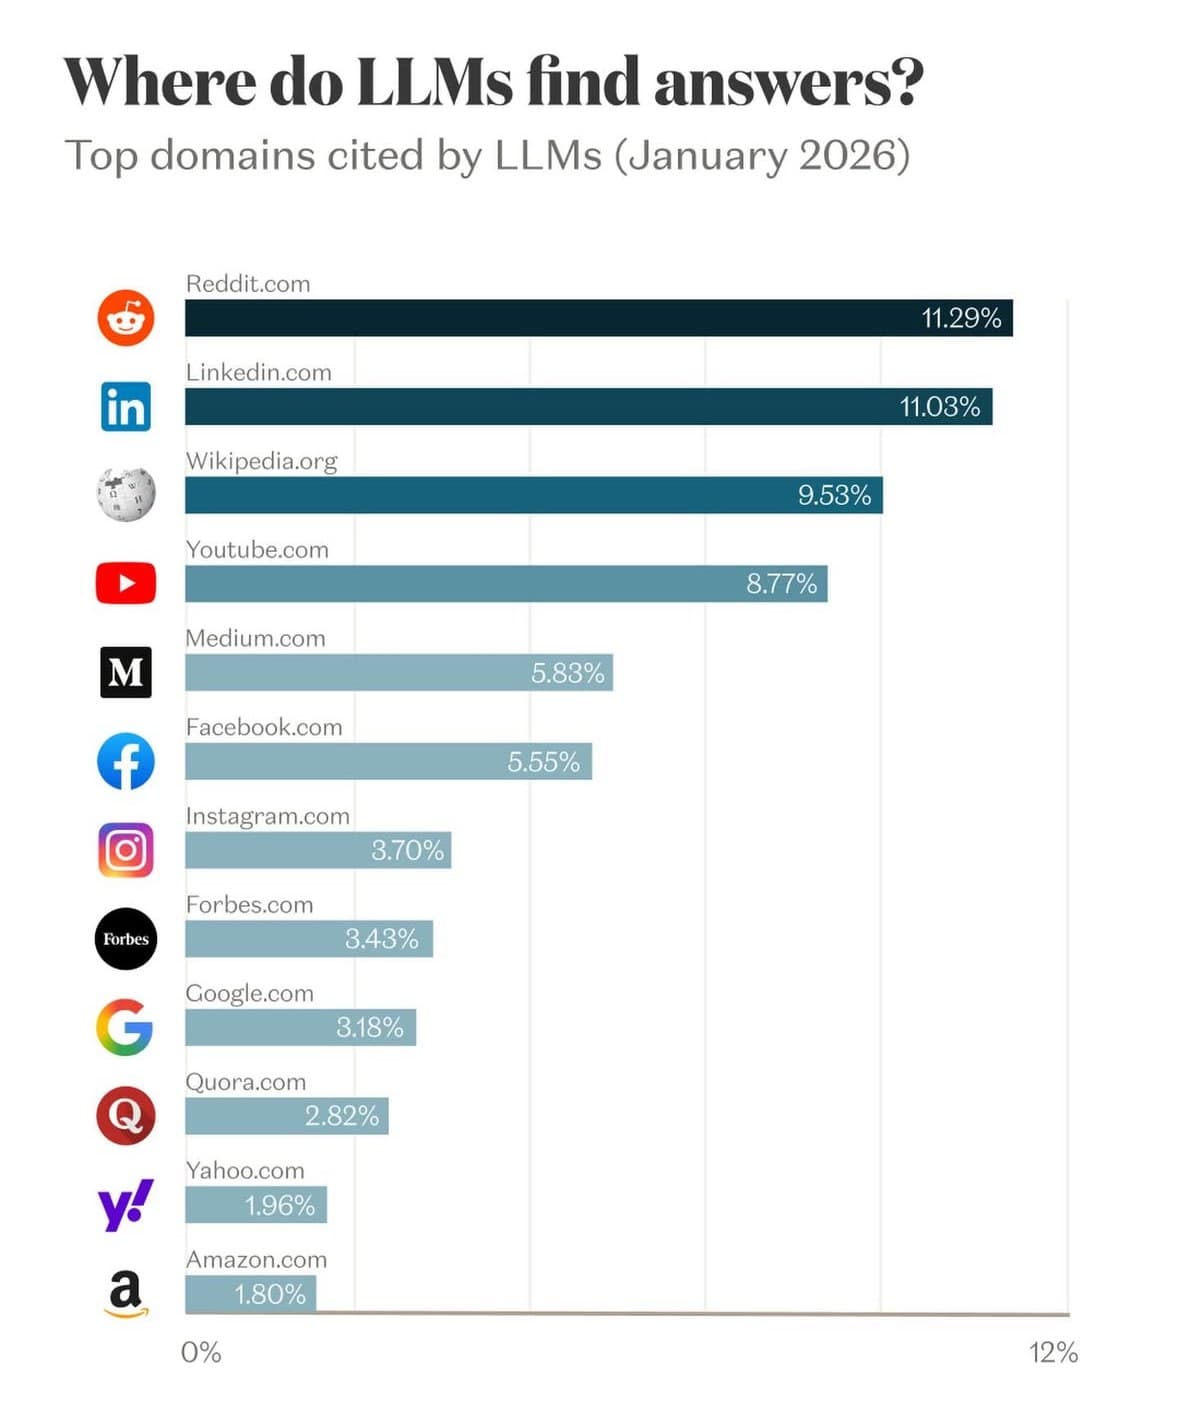
We start by asking the models the questions your buyers ask. That snapshot is the baseline: prompt-level visibility, share of answer, competitor positions. No invented citation percents. Just what the answers already print.
The Narrative Map turns that gap into claims you should own. Each placement exists to move a prompt, not to fill a clip book. After work ships, GEOview is the before and after.
It is not a GEO-only shop. On-site schema, FAQs, and llms.txt help a model read you. They do not mint the third-party proof the model prefers. GEOview sits inside narrative engineering. Measurement without placements is a report of the gap.
Book a 30-minute strategy session.
Book a strategy session